Why most AI pilots stall before production, and how to ship yours
IDC found that only 4 of every 33 AI proofs of concept reached production. The model is rarely the reason; here is what separates the pilots that ship from the ones that stall.
Listen to the summary ·
Read the transcript
IDC found that for every 33 AI proofs of concept a company launched, only four reached production. MIT NANDA’s 2025 report found that only about 5% of the AI pilot programs it studied achieved rapid revenue acceleration. The studies measure different things, but the model is rarely the reason.
Pilots stall for four reasons. There is no business metric, so the end of the pilot produces a debate instead of a decision. The demo data is cleaner than production data. Nobody planned the integrations with systems of record. And no team owns the system after launch.
BCG’s 10-20-70 rule holds that only about 10% of the value of an AI transformation comes from the application itself. Data and technology account for 20%, and redesigning workflows, culture and governance for 70%.
Pilots that ship start from one workflow and one number. They prototype on real production data in week two, design the integrations and human hand-offs before choosing a model, and launch narrow before widening scope.
Write the stop criteria down before the pilot starts. A pilot should end in one of three decisions: continue, change or stop. Two rounds of change on the same check usually mean stop.
The guide below has a production-readiness checklist and the questions to answer before a pilot begins.
AI-generated voice summary of this guide.

Every leadership team has seen the demo: a chatbot that answers questions about the company handbook, or an agent that drafts a customer reply in seconds. Six months later, almost none of them are in production.
The failure pattern is consistent, and it is not about model quality. Pilots are built under ideal conditions — clean sample data, a friendly test group, no integrations. Production removes every one of those assumptions at once.
The four reasons pilots stall
- No business metric. Teams measure whether the tool “works”, not whether it moves cost, revenue or cycle time.
- Data that isn’t ready. Curated demo data hides the messy, partial inputs real systems produce.
- No integration plan. An agent that can’t read from or write to your systems of record is a toy.
- Unclear ownership. AI teams, IT and the business unit each assume someone else will run it.
Each of these is invisible in a demo. Without a metric, the end of the pilot produces a debate instead of a decision, and debates tend to end in “not yet”. Without real data, the first week in production surfaces scanned PDFs, missing fields and edge cases the prototype never saw. Without integrations, someone has to copy results into the CRM by hand, and the time saved disappears. And without an owner, nobody updates prompts, watches costs or answers the first support ticket.
- Clean sample data
- A friendly test group
- No integrations
- Scanned PDFs, missing fields and edge cases
- Real users
- Reads from and writes to systems of record
“A successful demo answers whether the model can work. Production readiness asks whether the whole system keeps working under real conditions.”
What the research says
Four widely cited studies agree on the direction, though each measures something different. Read the “what it measured” column before quoting any of them.
| Study | Sample | Finding | What it measured |
|---|---|---|---|
| IDC with Lenovo, via CIO.com (March 2025) | Companies’ AI proofs of concept | “88% of observed POCs don’t make the cut to widescale deployment”; 4 of every 33 reached production | Proofs of concept reaching production |
| S&P Global Market Intelligence, via CIO Dive (March 2025) | More than 1,000 respondents in North America and Europe | 42% of businesses scrapped most AI initiatives, up from 17% a year earlier; the average organization scrapped 46% of proofs of concept before production | Initiatives abandoned |
| MIT NANDA, The GenAI Divide, via Fortune (August 2025) | AI pilot programs studied for the report | About 5% achieved rapid revenue acceleration | Measurable P&L impact |
| Gartner (June 2025) | Forecast | Over 40% of agentic AI projects will be canceled by the end of 2027 | Predicted cancellations |
Industry research points the same way on causes too. BCG’s 10-20-70 rule holds that only about 10% of the value of an AI transformation comes from the AI application itself, 20% from the underlying data and technology, and the remaining 70% from redesigning workflows, culture and governance. Gartner’s forecast is blunter: more than 40% of agentic AI projects canceled before 2028, and the reasons it gives (rising costs, value nobody can show, weak risk controls) are all about how the project is run, not which model it uses.
Gartner’s June 2025 forecast also warned about “agent washing”, the rebranding of existing assistants, RPA and chatbots as agents, and described most agentic projects at the time as early experiments driven by hype. The MIT NANDA report adds a finding about how companies build: according to Fortune’s summary, buying from specialized vendors and building partnerships succeeded about 67% of the time, while internal builds succeeded about a third as often. Read together, the message is that the bottleneck is organizational and architectural, not the model. We weigh the build-or-buy question in more depth in build vs buy AI agents.
What the 5% do differently
- Start from one workflow and one numberHours saved, tickets deflected, loans decided.
- Week 2Prototype on real production dataIn week two, not month six.
- Design the integration and the human hand-offBefore choosing a model.
- Ship a narrow version to real usersMeasure, then widen scope.
The order matters. Picking the workflow and the number first decides which data you need, which systems the agent must touch, and where a person stays in control. Choosing a model is one of the last decisions, and the easiest to change later.
A production-readiness checklist for AI agents
Before an agent goes live, every item below should have an owner and an answer:
- Metric and baseline: the number the agent must move, measured before launch so improvement can be proven.
- Evaluation set: real past cases with the correct outcome, rerun on every change to prompts, models or tools.
- Integrations: read and write access to the systems of record, with error handling, rate limits and a rollback path for writes.
- Permissions: the agent sees only what the user it acts for may see, enforced outside the model. Our list of production guardrails covers how.
- Human approval: consequential actions, such as sending, paying or deleting, wait for a person until the data shows they can be automated.
- Audit log: every input, tool call, output and approval is recorded and searchable.
- Monitoring: accuracy, exception rate, latency and cost per task tracked weekly, with alerts.
- Ownership: a named team that runs the system, handles support and decides on changes.
None of this is exotic. It is the same discipline any production software needs, applied to a component that behaves less predictably than ordinary code. If what you have is an app built with an AI app builder rather than an agent, the matching list is our checklist for taking a vibe-coded app to production, and our prototype to production service does that work for you.
Questions to answer before you start a pilot
Most failed pilots could have been predicted on day one. Before committing budget, answer these in writing:
- Which single workflow will change, and who does it today?
- Which number will prove success, what is it now, and what result would justify a full build?
- Where will the data come from in production, and have we looked at a real sample, not a cleaned one?
- Which systems must the agent read from or write to, and who owns access to them?
- Which actions need a person’s approval, and who is that person?
- Who will run the system after launch, and what budget covers running costs?
If any answer is “we’ll figure it out later”, that is where the pilot is most likely to stall. A good discovery phase exists to turn each of these into a concrete answer before the build is priced.
When to stop a pilot: continue, change or kill
A pilot should end in one of three decisions, and the criteria for each should be written down before it starts. Without them, a stalled pilot drifts for months because nobody wants to call it.
| Check | Continue to a build | Change and re-test | Stop |
|---|---|---|---|
| Agreed metric vs baseline | Moved past the threshold on real data | Moved, but short of the threshold | Did not move, or nobody measured it |
| Evaluation set on real cases | Passes the agreed mark | Fails on a known, fixable class of cases | Fails across the board, or no set exists |
| Integrations | Access confirmed and a write path tested | Access pending a named approval | A required system cannot be reached at acceptable cost |
| Owner after launch | Named team and budget | Owner agreed, budget not yet | Nobody will own it |
| Run cost per task vs value per task | Cost clearly below value | Close; routing or caching could close the gap | Cost above value at expected volume |
“Change” is the most common honest answer, and it should come with one specific change and a date for the re-test. Two rounds of “change” on the same check usually mean “stop”. We don’t publish universal thresholds, because a 10% gain is a win in one workflow and noise in another; what matters is that the number exists before the pilot does.
Two examples from our own builds
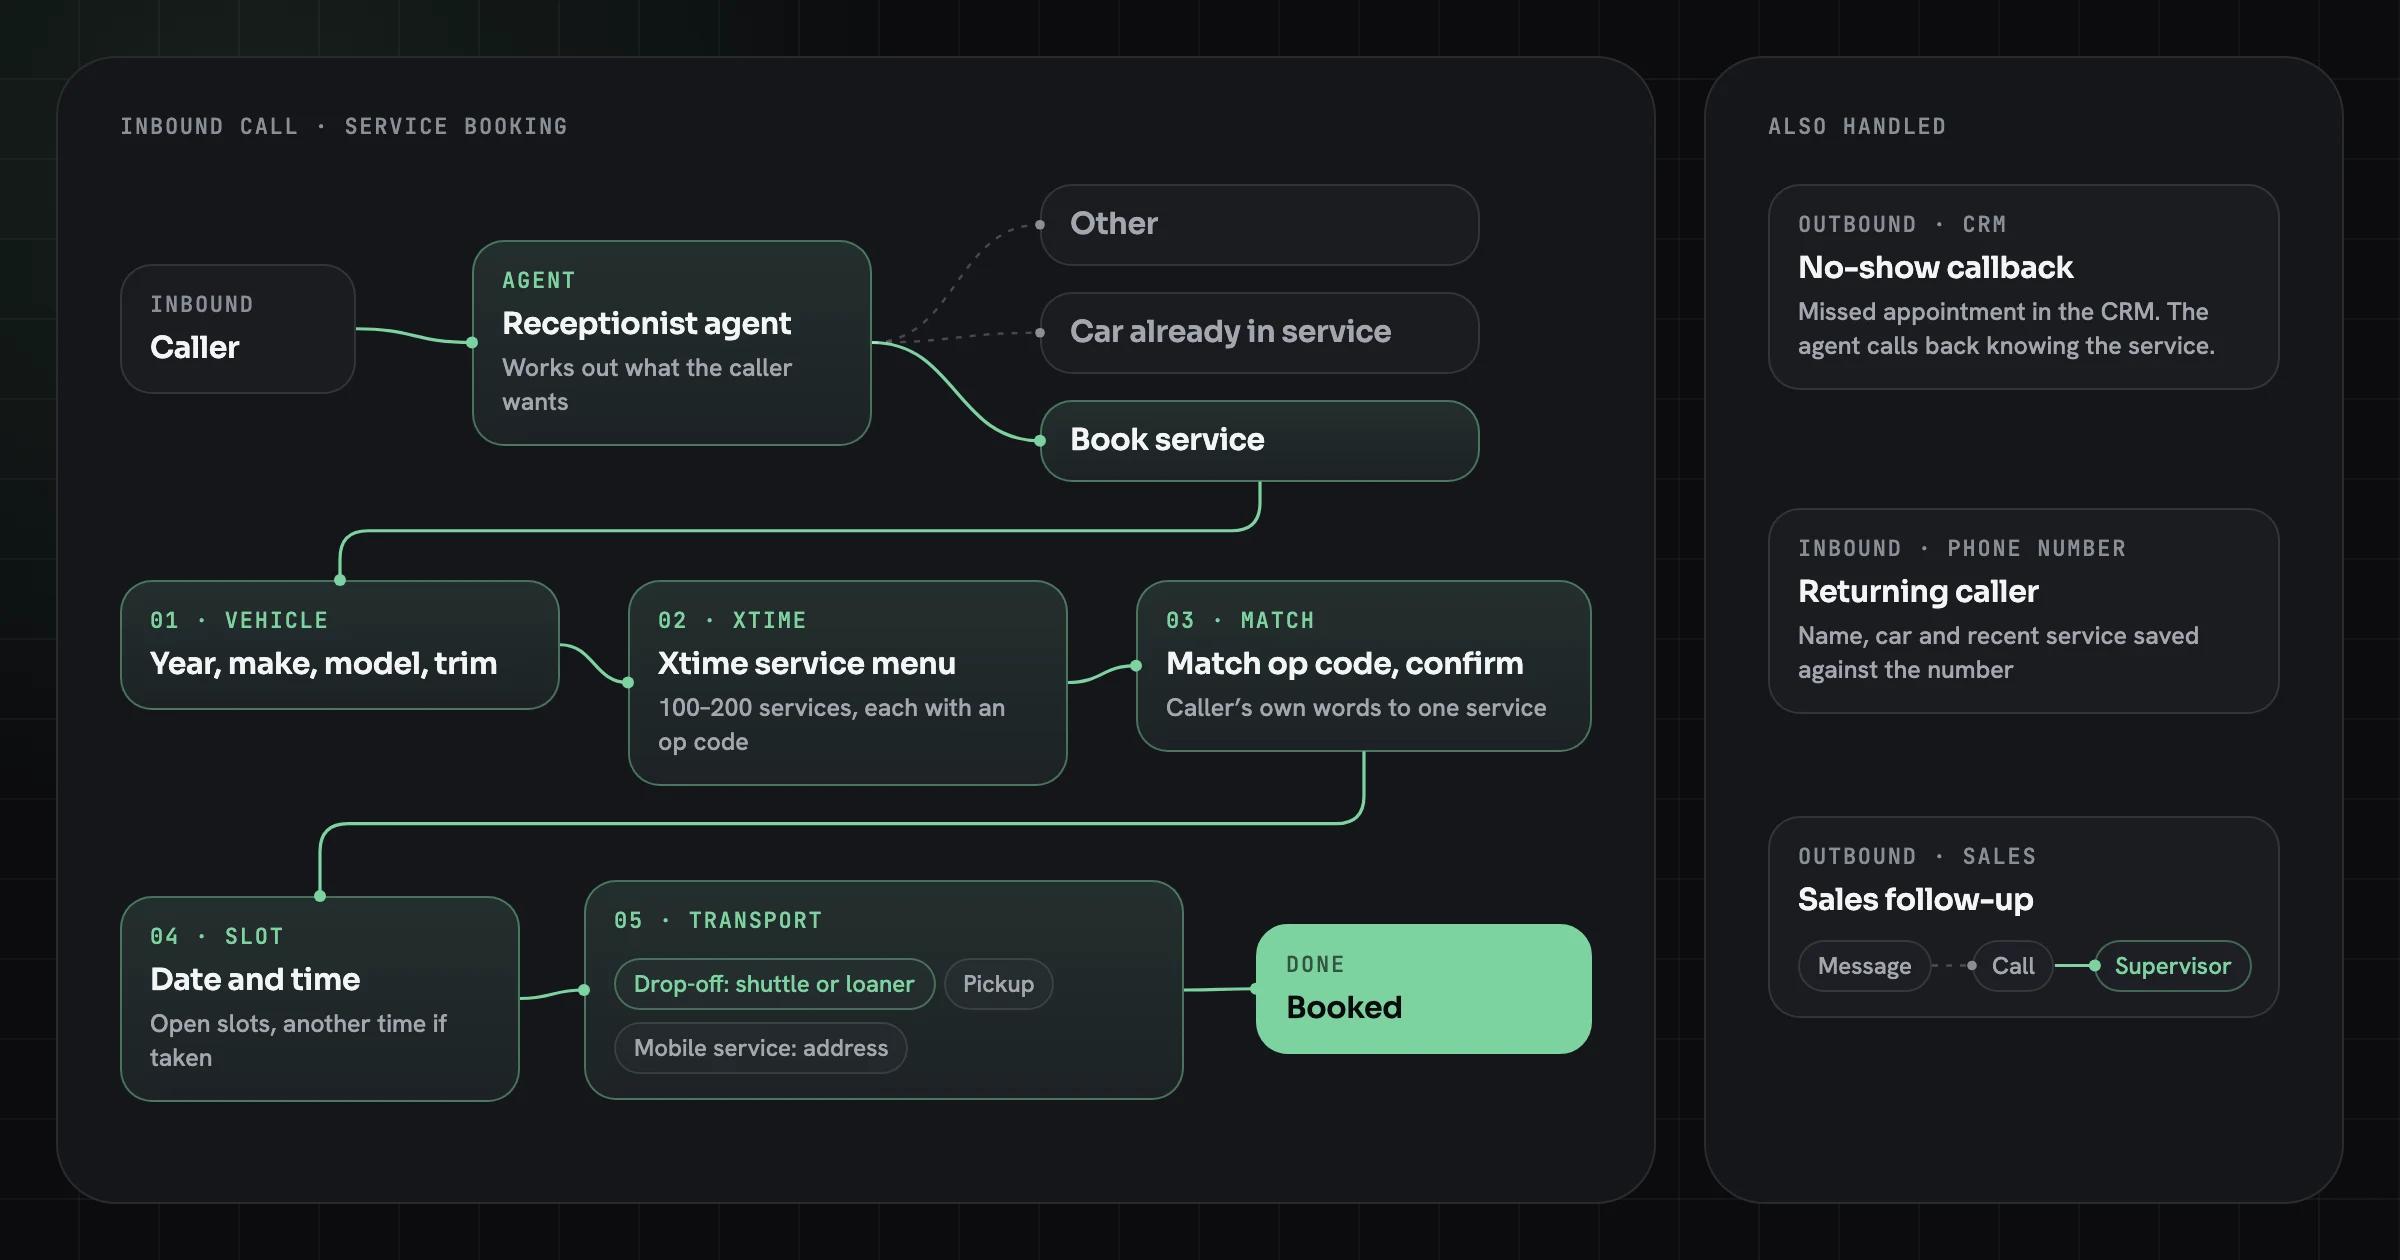
Superdeal avoids the integration trap: its agent works inside the same campaign workspace as the creators, deals, deliverables and shipments, so nothing is copied between tools and the time it saves stays saved. And nothing the agent drafts is sent until someone on the brand’s side approves it.
Relm, a multi-agent system for commercial real estate due diligence, had a trust problem to solve before a usage one: an analyst will not put a number from an AI into an investment memo unless they can check it. So every finding links to its source record, and each client firm’s data is kept apart at every layer the AI touches, from storage to the model’s context. Those two choices are what let an analyst rely on it.
Structure the engagement for production, not for a demo
We structure our own engagements around the questions above. The Discovery Sprint takes two weeks, costs $5,000 (credited to the build) and ends with a working prototype on your data. It answers the questions that sink pilots: is the data good enough, which integrations are needed, where must a person approve, and what will it cost to run. The build that follows is quoted at a fixed price and usually takes 6–16 weeks, delivered in two-week sprints with live demos and billed against working features. So the path from first workshop to a production launch is two weeks of discovery plus the build, not an open-ended pilot phase.


You can see the plans on our pricing page, what drives the number in AI agent development cost, and why we prefer this contract shape in fixed price or time and materials.
If you have a pilot that stalled, or one you want to get right the first time, our AI agent development team can take it from prototype to production.
Sources
- Gartner Predicts Over 40% of Agentic AI Projects Will Be Canceled by End of 2027, Gartner (June 25, 2025)
- MIT report: 95% of generative AI pilots at companies are failing, Fortune, on MIT NANDA’s The GenAI Divide (2025)
- AI Transformation (the 10-20-70 rule), Boston Consulting Group
- 88% of AI pilots fail to reach production — but that’s not all on IT, CIO.com, on IDC research with Lenovo (March 25, 2025)
- AI project failure rates are on the rise: report, CIO Dive, on S&P Global Market Intelligence (March 14, 2025)
AI Agent Development
We design and build autonomous AI agents and multi-agent systems that read, decide and act across your tools, with human approval where it matters.
